OpenGrade
Unit tests for your LLM app. Trace it, score it on a test set, and fail the pull request when answer quality drops — self-hosted, one package, no SaaS.
The problem
You change a prompt, swap the model or tweak the retriever. The demo still looks fine. A week later users notice that the assistant now invents answers it used to get right.
Normal tests can't catch this: the output is text, and "correct" is a judgement. OpenGrade turns that judgement into numbers you can compare between two versions of your app, and into an exit code your CI understands.
A pull request breaks the retriever. Every absolute threshold still passes, but compared with
the last accepted run on main, question by question, the gate blocks it:
Test cases worse than baseline (4):
  ▼ How do I book business travel?
      hit_at_k: 1.000 PASS → 0.000 FAIL
      baseline:  Business travel must be booked through Navan at least 14 days in advance.
      candidate: Payroll is processed on the last business day of each month.
  ...
│ hit_at_k.min                     │ 0.8   │ 0.8    │ passed │
│ regression.hit_at_k.mean_score   │ -0.20 │ -0.05  │ failed │
│ regression.hit_at_k.new_failures │ 4     │ 0      │ failed │
Result: FAILED          ← exit code 1, the PR is red
Try it
from opengrade import Opengrade

og = Opengrade(project="support-bot")

@og.trace
def answer(question: str) -> str:
    docs = retriever.search(question)
    og.set_retrieval_documents(docs)
    return llm.generate(question, docs)

result = og.evaluate(
    dataset="gold.jsonl",
    task=lambda item: answer(item.input),
    metrics=["hit_at_k", "groundedness", "correctness"],
    baseline="alias:main",
)
Good fit: answers that can be checked against something — RAG and Q&A assistants, classification, extraction, tool calls with a fixed schema. Not a fit: purely subjective output, or a general APM. Details: project overview.
User guide
- Getting started — 15 minutes: UI, first trace, a scored experiment
- How OpenGrade works — the end-to-end workflow: test sets, metrics, baselines, CI gate, production
- Python SDK — tracing, experiments, custom metrics and judges, control-plane client
- CLI and CI —
opengrade evaluate/opengrade check, policy reference, GitHub Actions - Metrics and judges — every built-in metric and LLM judge, and how it scores
- Evaluate a chat assistant — multi-turn test cases, conversation judges, sessions in production
- Custom evaluators — Python metrics, custom LLM judges, server evaluators
- Deploy — local server or Docker Compose with PostgreSQL, configuration, exposing it safely
- Security and API keys — trust model, keys, content capture
- Examples — runnable demos, from a first trace to a PR regression gate
- API reference — generated from the SDK docstrings
- Changelog — what changed in each release
Design notes
Internal specifications and decisions, for contributors (how to contribute).
- Project overview, architecture, domain model
- Tracing and OpenTelemetry, REST API, database, frontend
- Testing strategy, roadmap
- Architecture decisions: ADR-001 (OpenTelemetry/OpenInference), ADR-002 (PostgreSQL first)
Naming
| What you see | What it means |
|---|---|
| OpenGrade | Product name |
opengrade-ai |
PyPI SDK (import opengrade, console script opengrade) |
opengrade-ai-server |
PyPI API + packaged UI (opengrade_server, opengrade-server) |
opengrade ui / opengrade check |
CLI commands (need server / [ui] extra) |
Glossary
| Term | Meaning |
|---|---|
| Project | Workspace for traces, datasets and experiments (slug + id) |
| Trace | OTLP/OpenInference span tree of one request, ingested at /v1/traces |
| Dataset / test set | Versioned gold items (e.g. rag_qa questions with expected answers and documents). Test set in the UI, dataset in the SDK and API |
| Metric / evaluator | Scores one answer: deterministic, LLM judge, custom judge or local Python metric |
| Metrics set | Named, versioned set of metrics with thresholds scored on an experiment. Metrics pack in older routes (evaluate-pack, metrics_packs) |
| Experiment / run | One scored pass of your app over a dataset |
| Baseline / alias | The experiment a run is compared with; an alias (alias:main) points to the last accepted one |
| Quality gate | YAML policy + opengrade evaluate / opengrade check: exit codes for CI |
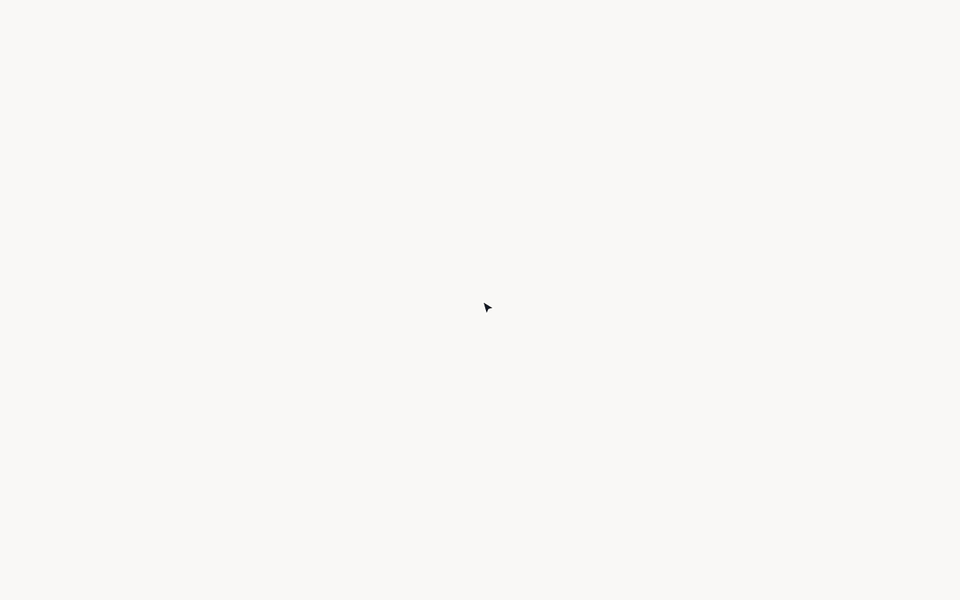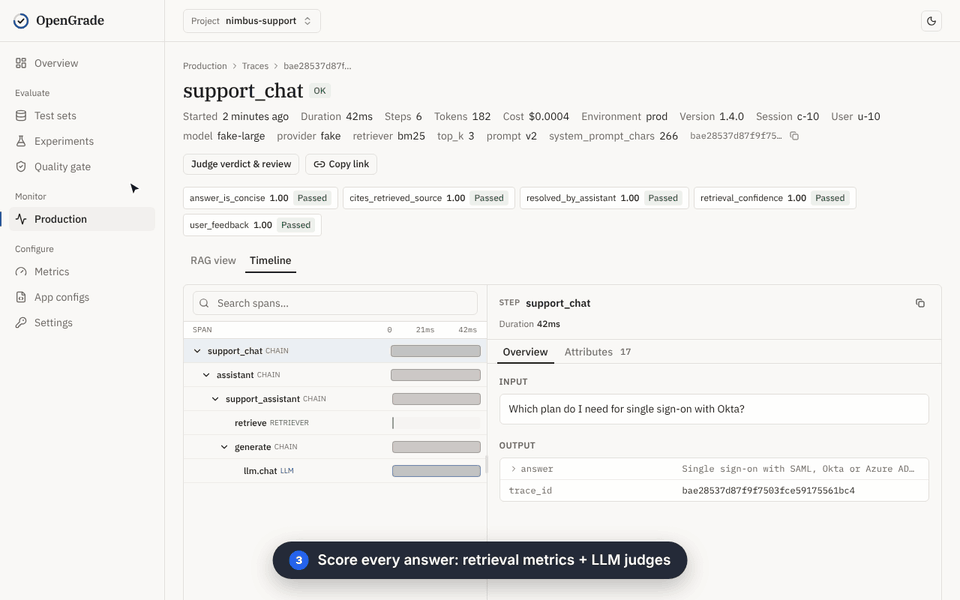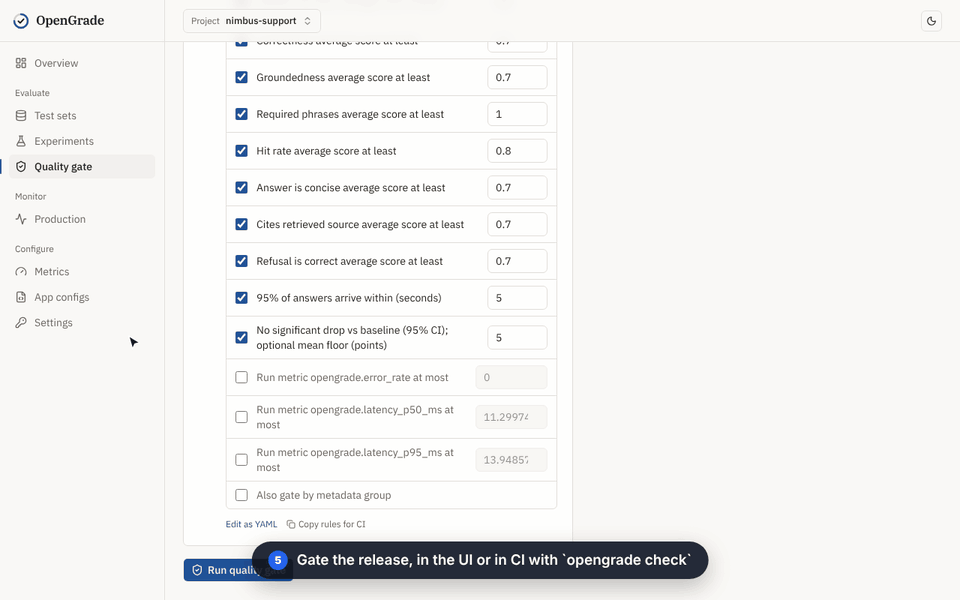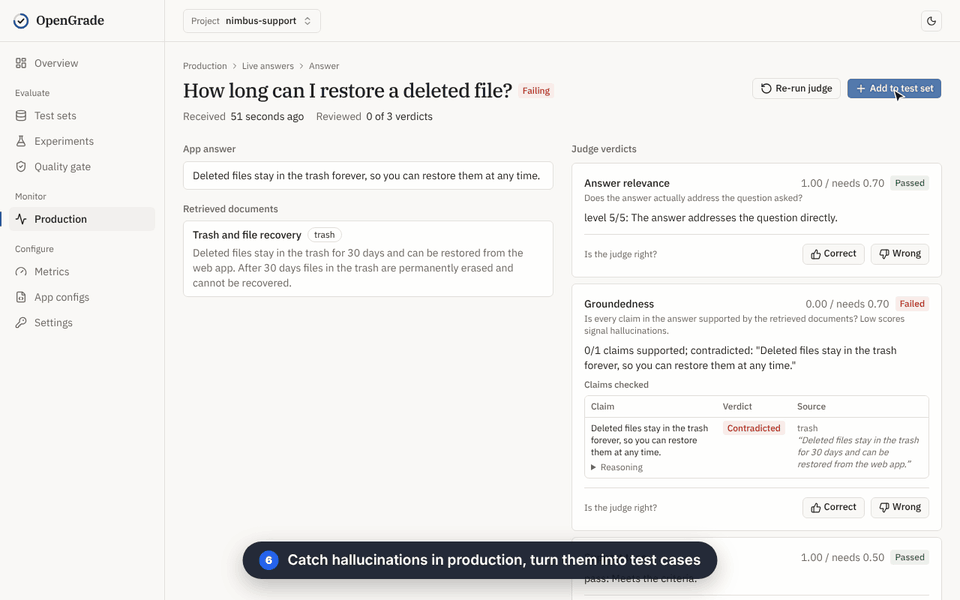
| Live interaction / live run | Production request scored without gold; can be promoted into a dataset |
Primary loop: project → dataset → metrics set → experiment → compare with the baseline → quality gate → production → promote into the dataset. Explained step by step in How OpenGrade works.